GPU hardware
Compare GPU and server options. We confirm price, availability, and delivery in each quote.
Filter hardware
7 products
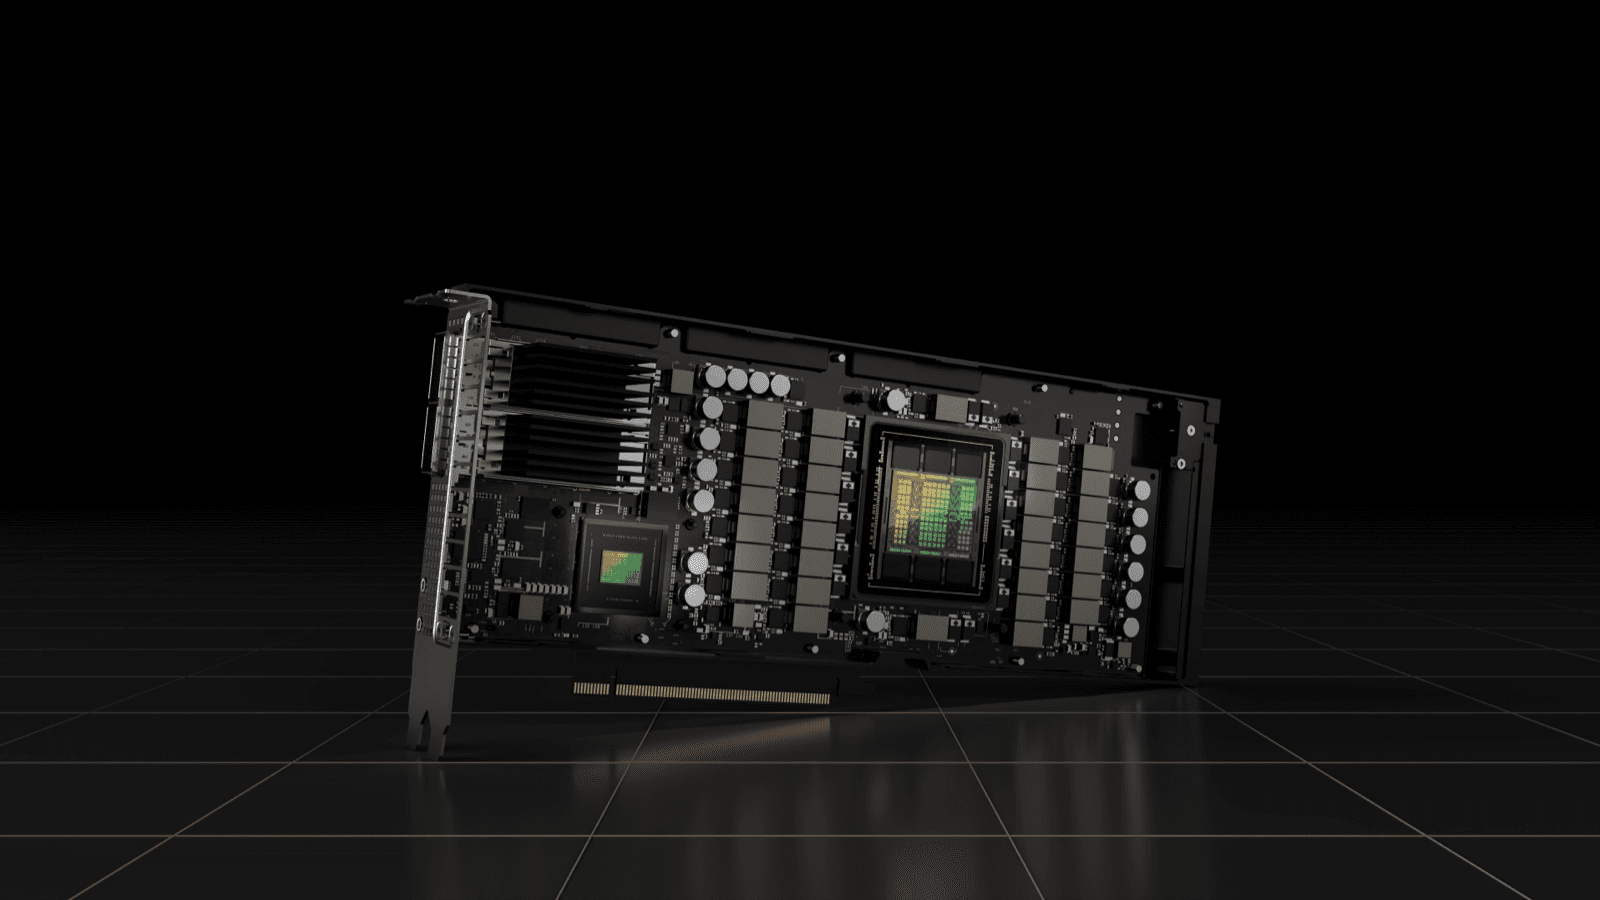
NVIDIA H100 80GB PCIe Gen5
NVIDIA H100 PCIe accelerator with 80GB of HBM2e. Fits supported PCIe server platforms for training and inference. Request a current configuration and quote.
Current quote on request

NVIDIA H100 80GB SXM5
NVIDIA H100 SXM GPU with 80GB HBM3, used in HGX server platforms. Request a complete OEM system quote with current delivery terms.
Current quote on request

NVIDIA H200 141GB HBM3e SXM5
Hopper GPU with 141GB HBM3e and 4.8TB/s bandwidth. A useful option for memory-heavy inference. Contact us for current availability and lead time.
Current quote on request

NVIDIA B200 180GB SXM
Blackwell GPU with 180GB HBM3e per GPU in 8-GPU HGX systems. Ask us for a complete OEM server quote with current availability and lead time.
Current quote on request
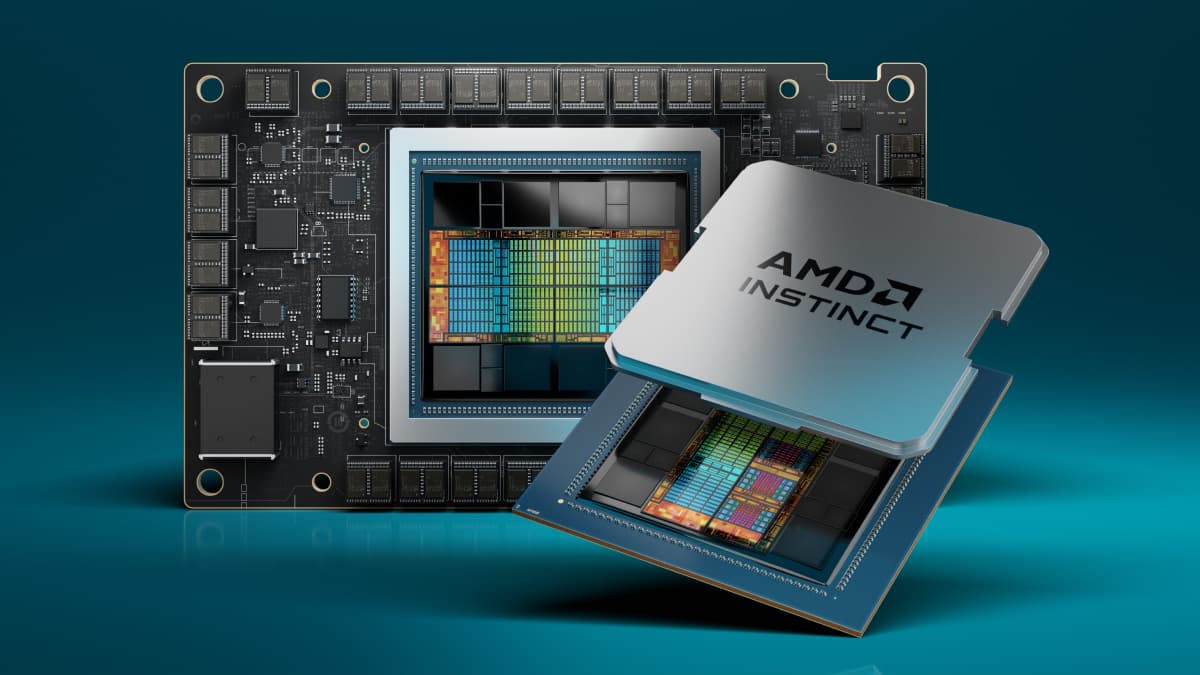
AMD Instinct MI300X 192GB HBM3 OAM
AMD Instinct MI300X offers 192GB HBM3 and 5.3TB/s bandwidth. It can be useful for memory-heavy inference when the software stack supports ROCm. Quoted per project with availability confirmed in writing.
Current quote on request
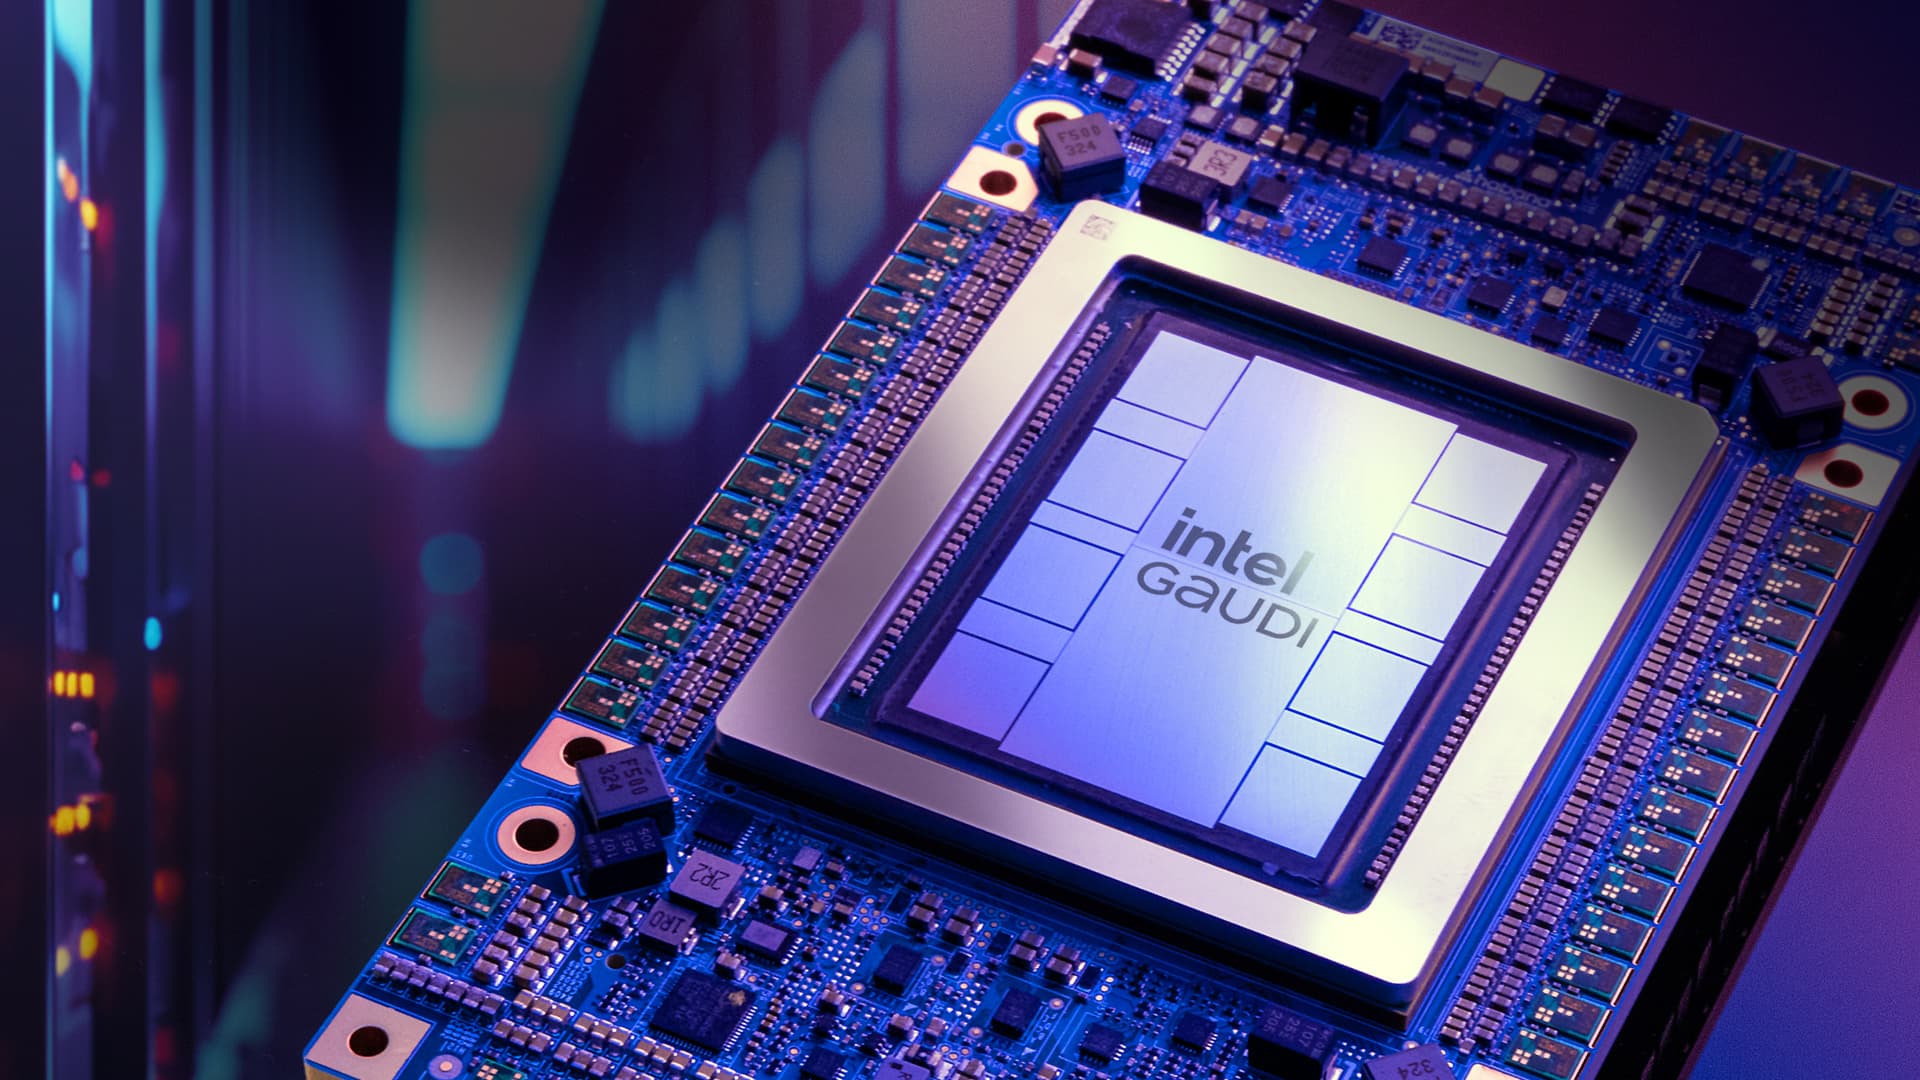
Intel Gaudi 3 AI Accelerator
Intel's third-gen AI accelerator optimized for LLM training and inference. Cost-effective alternative with Ethernet-based scaling. Contact us for evaluation units and pricing.
Current quote on request
  ╔═══════╗
  ║ ▓▓▓▓▓ ║
  ║ ▓▓▓▓▓ ║
  ╚═══════╝
    GPU
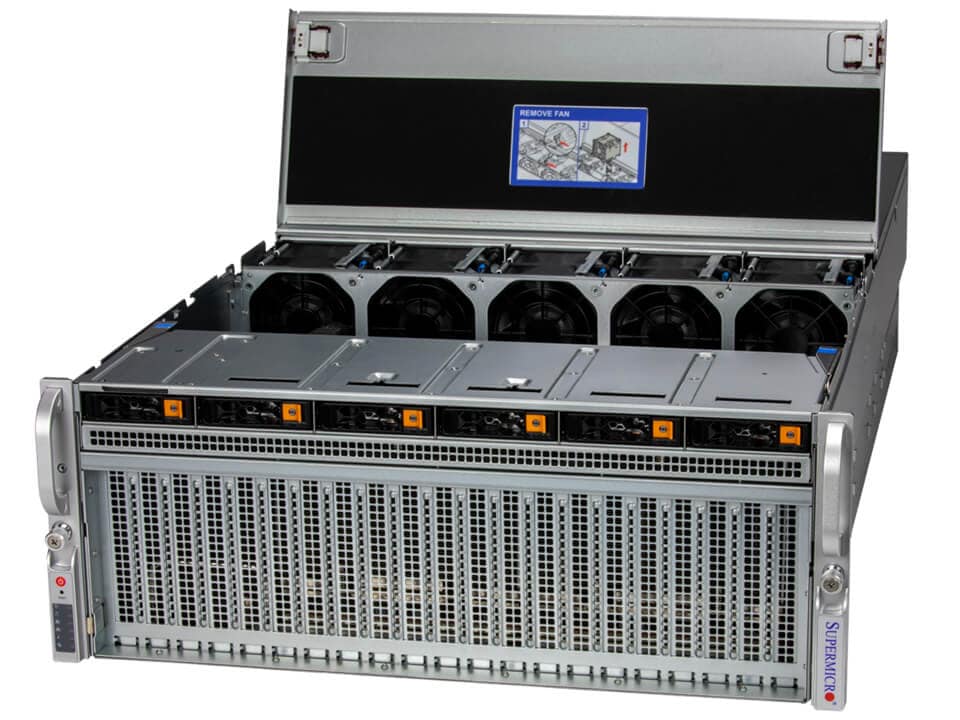
Supermicro SYS-421GE-TNHR2-LCC 8x H200 Server
Supermicro's 4U liquid-cooled HGX H200 system supports eight 141GB GPUs. This model requires complete liquid-cooled rack integration and on-site service. CPU, RAM, storage, networking, and delivery are configured in the quote.
Current quote on request
Before You Buy
Research that prevents expensive hardware mistakes
Use the catalog with the relevant guides nearby: market timing, VRAM sizing, power envelopes, and buy-vs-rent tradeoffs.
AMD MI350X vs NVIDIA B200: What a Buyer Should Compare
Compare MI350X and B200 memory, software, OEM systems, cooling, and the details needed for a useful quote.
QLoRA vs LoRA: Complete Fine-Tuning Guide for LLMs
Learn when to use LoRA vs QLoRA for LLM fine-tuning. Includes memory requirements, GPU recommendations, code examples, and cost analysis for fine-tuning Llama on different hardware.
H100 vs H200: Choosing a Hopper Server
Compare H100 and H200 memory, bandwidth, server fit, and the details needed for current quotes.