
NVIDIA H200 141GB HBM3e SXM5
Hopper GPU with 141GB HBM3e and 4.8TB/s bandwidth. A useful option for memory-heavy inference. Contact us for current availability and lead time.
Price Available Upon Request
We confirm the configuration, price, delivery estimate, and warranty terms before you order.
What it's for
The NVIDIA H200 Tensor Core GPU has 141GB of HBM3e memory and up to 4.8TB/s bandwidth. The larger memory footprint can help with inference workloads that do not fit comfortably on H100. Contact us for a current configuration and quote.
Key Features
- ✓141GB HBM3e memory - nearly 2x the capacity of H100
- ✓4.8 TB/s memory bandwidth - 1.4x faster than H100
- ✓1,979 TFLOPS FP8 performance with Transformer Engine
- ✓Fourth-generation Tensor Cores with FP8 precision
- ✓Multi-Instance GPU (MIG) support
- ✓NVLink for multi-GPU server integration
- ✓Secure Boot and confidential computing support
- ✓Full compatibility with NVIDIA AI Enterprise software
Use Cases
- →Large Language Model (LLM) training and inference
- →Generative AI and foundation model development
- →Recommendation systems at scale
- →Scientific computing and molecular dynamics
- →Computational fluid dynamics (CFD)
- →Weather simulation and climate modeling
Technical Specifications
| Architecture | Hopper |
| GPU Memory | 141 GB HBM3e |
| Memory Bandwidth | 4.8 TB/s |
| FP64 Performance | 60 TFLOPS |
| FP32 Performance | 120 TFLOPS (TF32) |
| FP16 Performance | ~990 TFLOPS |
| FP8 Performance | ~1,979 TFLOPS |
| INT8 Performance | ~3,958 TOPS |
| CUDA Cores | 16,896 |
| Tensor Cores | 528 (4th Gen) |
| NVLink | 900 GB/s (18 links) |
| Max TDP | 700W |
| Thermal Solution | Air or liquid, depending on OEM system |
| Form Factor | SXM5 |
| PCIe Interface | PCIe Gen5 x16 |
Manufacturer references
Related Products
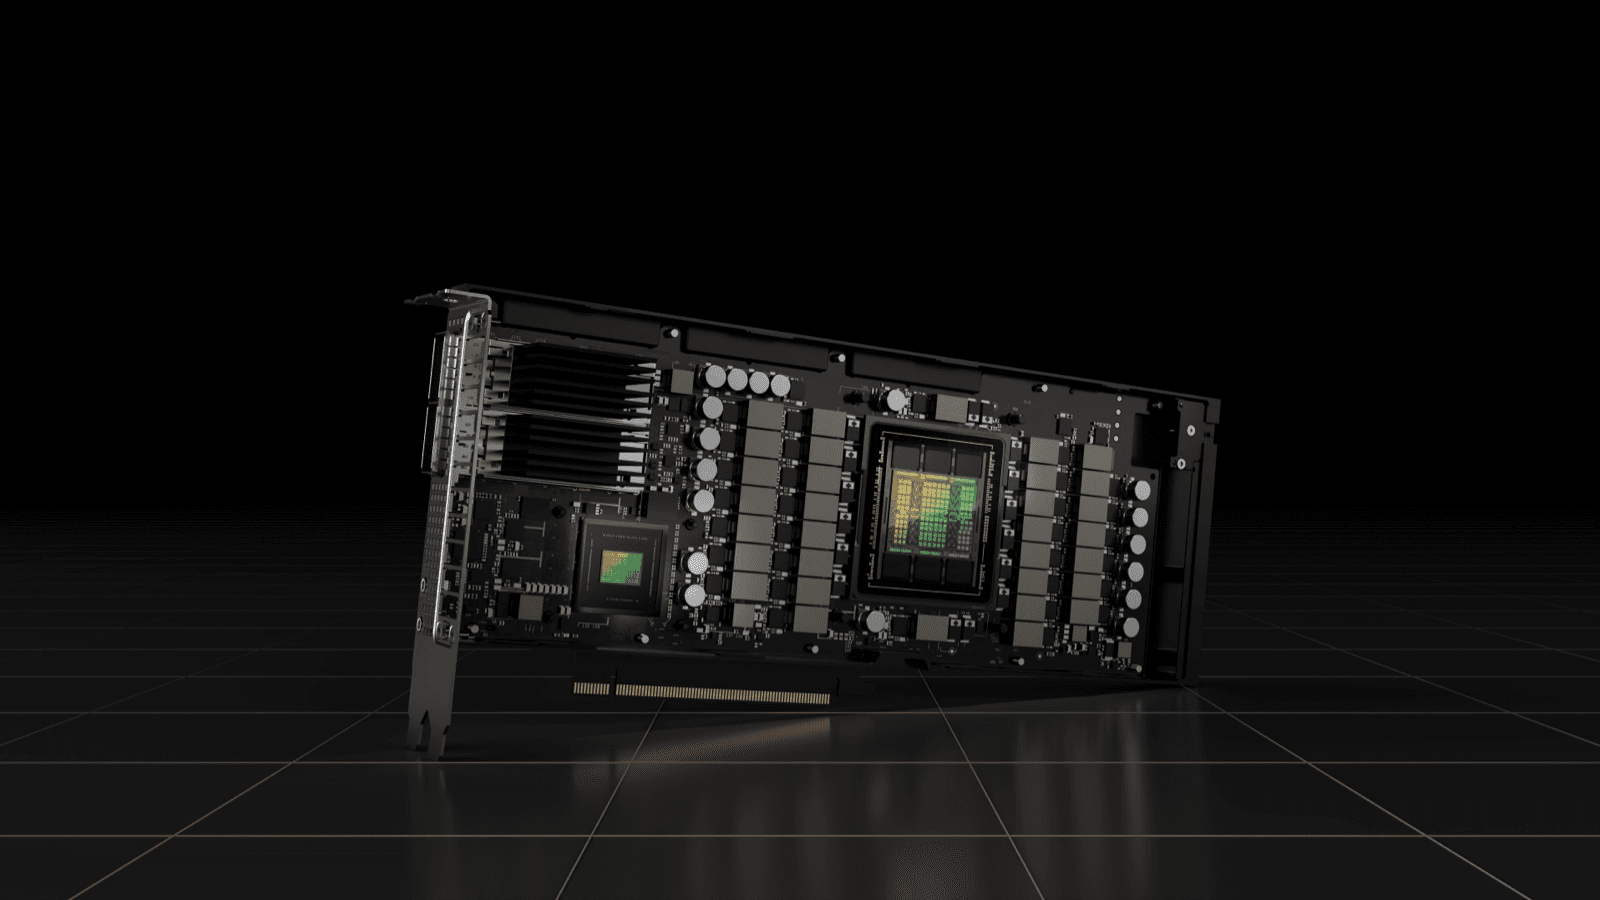
NVIDIA H100 80GB PCIe Gen5
NVIDIA H100 PCIe accelerator with 80GB of HBM2e. Fits supported PCIe server platforms for training and inference. Request a current configuration and quote.
Current quote on request

NVIDIA H100 80GB SXM5
NVIDIA H100 SXM GPU with 80GB HBM3, used in HGX server platforms. Request a complete OEM system quote with current delivery terms.
Current quote on request

NVIDIA B200 180GB SXM
Blackwell GPU with 180GB HBM3e per GPU in 8-GPU HGX systems. Ask us for a complete OEM server quote with current availability and lead time.
Current quote on request
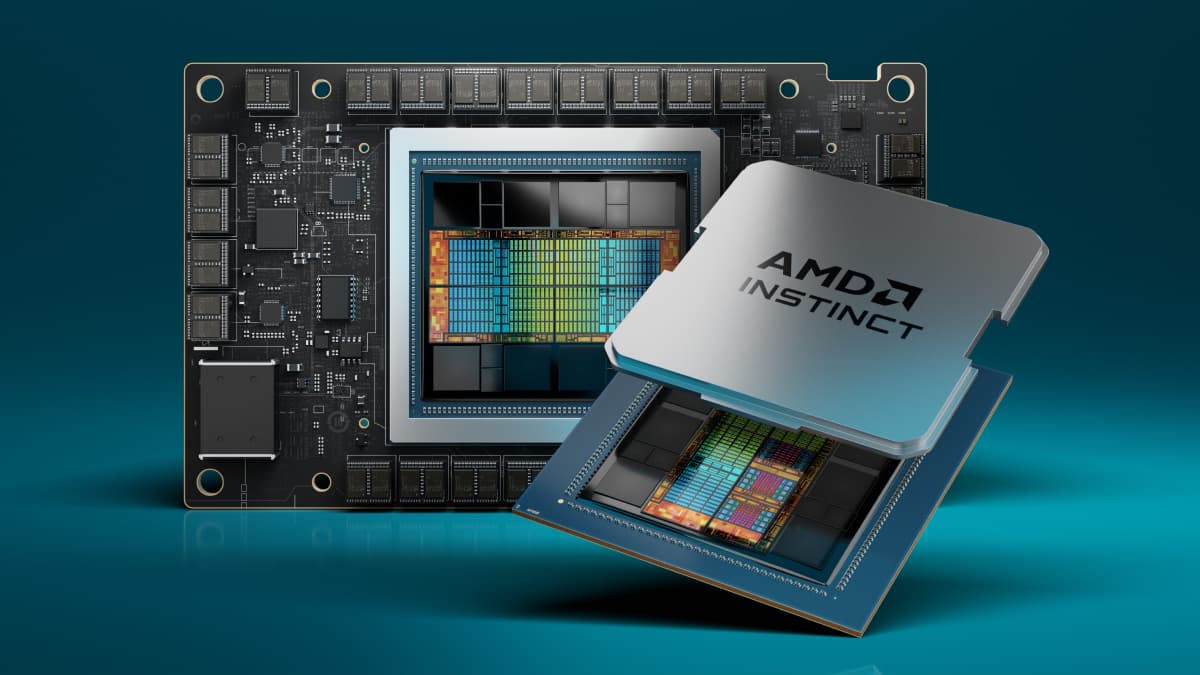
AMD Instinct MI300X 192GB HBM3 OAM
AMD Instinct MI300X offers 192GB HBM3 and 5.3TB/s bandwidth. It can be useful for memory-heavy inference when the software stack supports ROCm. Quoted per project with availability confirmed in writing.
Current quote on request
Recommended Reading
Related buying guides
Background on memory, power, cooling, and deployment planning.
GPU Memory Requirements for LLM Inference: How Much VRAM Do You Need?
A practical VRAM sizing guide for LLM inference: 7B, 13B, 70B, and 405B model classes, how quantization changes memory needs, and when to choose RTX 4090, L40S, H100, or H200.
H200 vs B200: Which NVIDIA GPU is Right for Your AI Workload?
Compare H200 and B200 memory, interconnect, software, cooling, and current quote requirements.
AI Infrastructure Market Update: Blackwell Clouds, MI350 Launch, and the New Floor for Useful Inference
The GPU market changed materially over the last year: Blackwell moved into real cloud deployments, AMD launched MI350, MLPerf shifted to 405B-scale benchmarks, and newer open-weight reasoning models reset what counts as a practical inference box.