
NVIDIA B200 192GB Blackwell
Blackwell architecture with 192GB HBM3e and FP4 precision for next-gen AI. Contact us for availability and pricing.
Price Available Upon Request
Custom configuration and pricing
What it's for
The NVIDIA B200 Tensor Core GPU is built on the new Blackwell architecture with 208 billion transistors. The B200's dual-die Blackwell design delivers 20 petaFLOPS of FP4 — about 5x H100 — with 192GB HBM3e at 8TB/s. It's engineered to handle the most demanding foundation models and trillion-parameter AI workloads. Contact us for availability and deployment planning.
Key Features
- ✓208 billion transistors in dual-die chiplet design - 2.6x more than H100
- ✓20 petaFLOPS FP4 performance - 5x faster than H100 for AI
- ✓192GB HBM3e memory with 8TB/s bandwidth
- ✓Second-generation Transformer Engine with FP4 arithmetic
- ✓Advanced NVLink with 1.8TB/s bi-directional throughput
- ✓TSMC N4P process node for maximum efficiency
- ✓Fifth-generation Tensor Cores with multi-precision support
- ✓Designed for trillion-parameter model training and inference
Use Cases
- →Foundation model training (GPT-4 scale and beyond)
- →Trillion-parameter AI model development
- →Real-time generative AI inference at scale
- →Multi-modal AI (text, image, video, audio)
- →Scientific computing and simulation
- →Drug discovery and genomics research
Technical Specifications
| Architecture | Blackwell (5th Gen) |
| GPU Memory | 192 GB HBM3e |
| Memory Bandwidth | 8 TB/s |
| Transistor Count | 208 billion |
| FP4 Performance | 20 petaFLOPS (sparse) |
| FP8 Performance | ~10 petaFLOPS |
| FP16 Performance | ~5 petaFLOPS |
| Tensor Cores | 5th Generation |
| NVLink Bandwidth | 1.8 TB/s bi-directional |
| Process Node | TSMC N4P |
| Max TDP | 1000W |
| Thermal Solution | Liquid cooling required |
| Form Factor | NVL72 dual-die package |
| Die Configuration | Dual-chip module |
Related Products
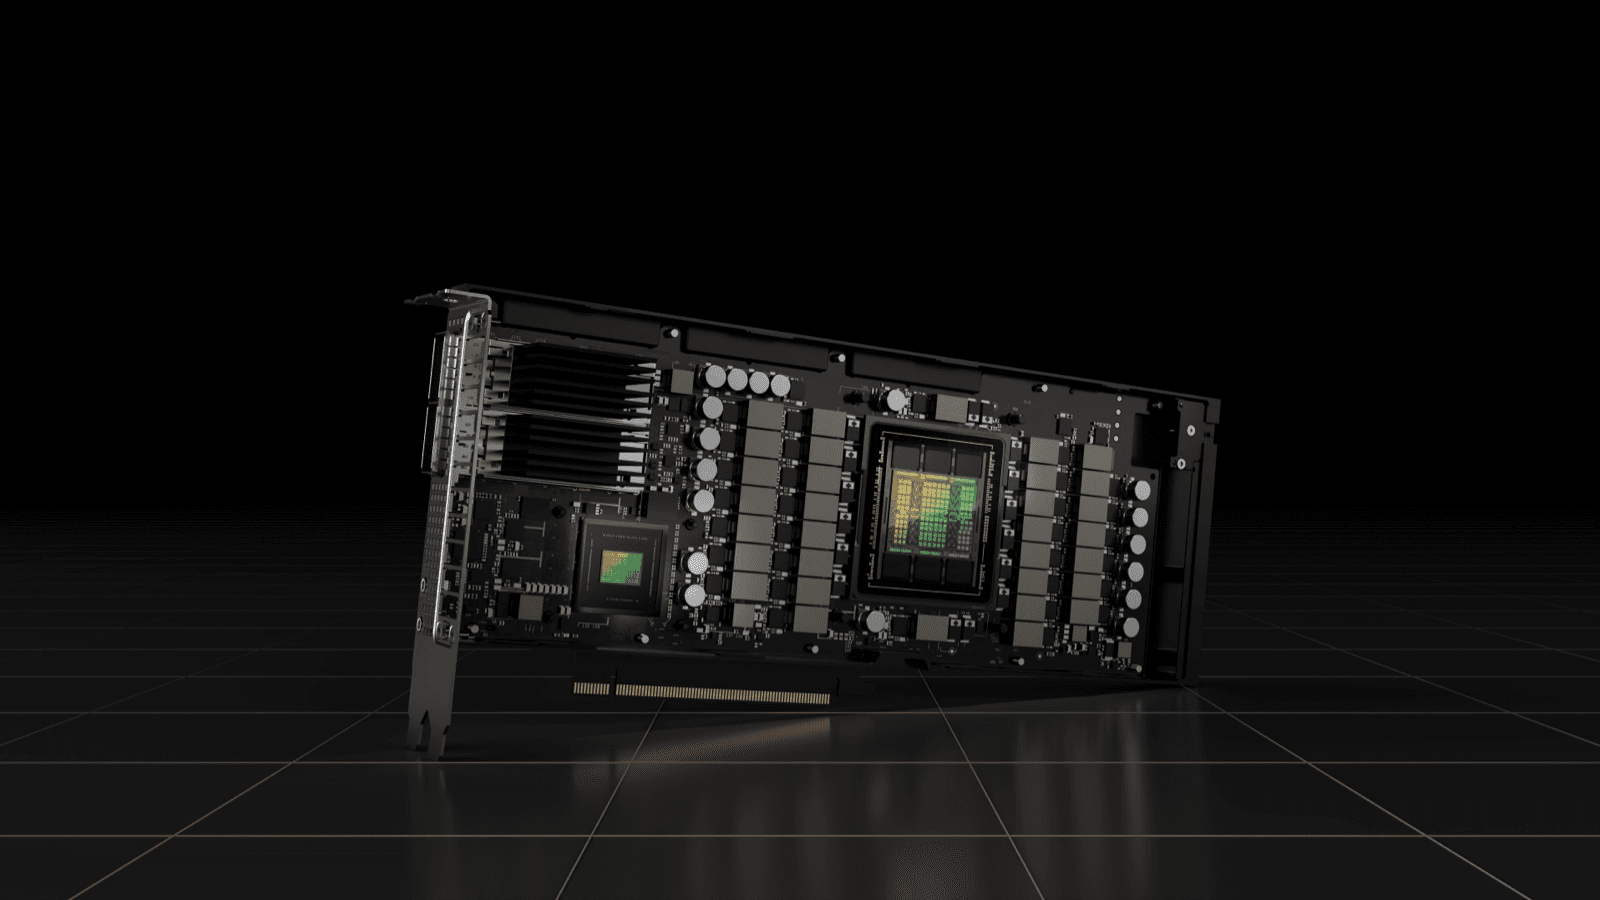
NVIDIA H100 80GB PCIe Gen5
NVIDIA H100 Tensor Core GPU in PCIe form factor with 80GB HBM3 memory. Ideal for deploying AI inference and training in standard servers without NVLink clustering requirements. Contact our sales team for volume pricing and current lead time.
From
$29,999

NVIDIA H100 80GB SXM5
NVIDIA H100 Tensor Core GPU in SXM5 form factor with NVLink for multi-GPU scaling. Designed for HGX server platforms and large-scale AI training clusters. Enterprise volume discounts available - contact sales for custom configurations.
From
$32,999

NVIDIA H200 141GB HBM3e SXM5
Hopper GPU with 141GB HBM3e and 4.8TB/s bandwidth — the memory-bandwidth pick for LLM inference. Contact us for current lead time.
From
$39,999
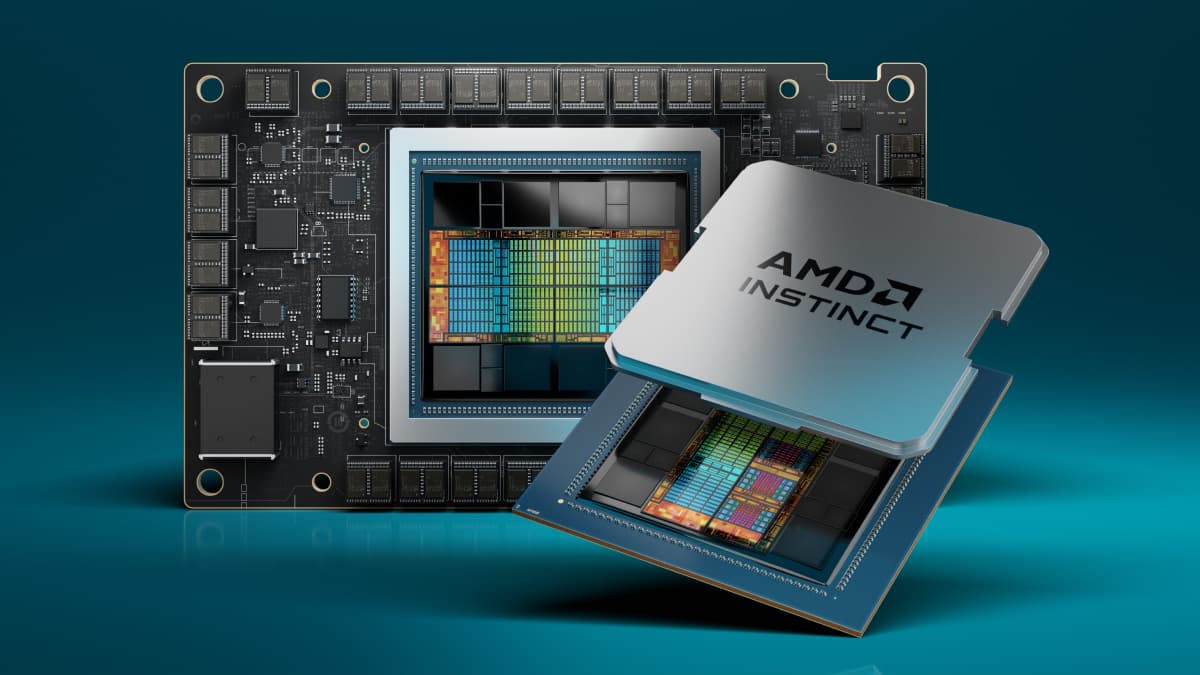
AMD Instinct MI300X 192GB HBM3 OAM
AMD's flagship AI accelerator with 192GB HBM3 — the largest single-GPU memory in the class — and 5.3TB/s bandwidth. Strong performance per dollar for generative AI and large language models. Quoted per project with ROCm support; lead time confirmed at quote.
From
$29,999
Recommended Reading
The adjacent decisions buyers usually miss
Relevant guides tied to this product's real deployment questions: VRAM, power, cooling, financing, and market timing.
AMD MI350X vs NVIDIA B200: Which Next-Gen AI GPU Should You Buy?
Side-by-side comparison of AMD MI350X (288GB, CDNA 4) and NVIDIA B200 (192GB, Blackwell): specs, inference benchmarks (MI350X 20-30% faster on large models), training performance, pricing (~50% cheaper), software ecosystem, and cooling requirements.
GPU Server Power Planning Guide: Circuits, PDUs, and Rack Budgeting
Plan power correctly before your GPU hardware lands. This guide covers circuit sizing, rack density, PDU planning, and realistic power envelopes for H100, H200, MI300X, and B200 systems.
Liquid Cooling for AI GPU Servers: Complete Datacenter Guide
Everything you need to know about liquid cooling for GPU servers: direct-to-chip vs immersion, CDU sizing, retrofit costs ($50K–$150K per row), and which GPUs require it. Essential reading before buying B200 or GB200.