Compare the hardware that matters for your workload. Start with memory and system format, then check software, cooling, and the complete server before requesting a price.
Hardware sourcing
Start with the workload. We can help narrow the build.
Tell us the GPU, quantity, destination, and timing you have in mind. We will check the configuration and current channel availability before giving you a price or delivery estimate.
Request a hardware quoteUseful to include
- GPU and quantityModel, GPU count, and whether a complete server or rack is needed.
- WorkloadTraining or inference, model size, framework, and any CUDA or ROCm requirement.
- FacilityDestination, available power, rack space, and air or liquid cooling.
- TimingTarget delivery date and whether an alternate configuration is acceptable.
Rent capacity
Useful for short projects, uneven demand, or testing a workload before buying hardware. Compare the GPU model, memory, interconnect, data location, and total hours you expect to use.
Buy hardware
Useful when demand is sustained and you can operate the system. Include power, cooling, network, support, and replacement planning in the cost comparison.
There is no universal break-even point. Utilization, cloud contract rates, facility cost, financing, and resale value change the result.
More memory can keep a larger model or batch on fewer GPUs. Software compatibility, network topology, and the complete server still decide whether a part fits your workload.
| GPU | Memory per GPU | System format | Where to start |
|---|---|---|---|
| H100 SXM | 80 GB HBM3 | HGX server | Established CUDA training and inference |
| H200 SXM | 141 GB HBM3e | HGX server | Memory-heavy inference and training |
| B200 SXM | 180 GB HBM3e | 8-GPU HGX server | Blackwell training and inference |
| MI300X | 192 GB HBM3 | 8-GPU OAM server | Large models on AMD ROCm |
| MI355X | 288 GB HBM3e | 8-GPU OAM server | High-memory AMD deployments with liquid cooling |
Figures describe manufacturer platforms. Exact server options vary by OEM.
A familiar starting point when CUDA support and an established HGX platform matter most.
H100 SXM has 80 GB of HBM3 memory per GPU. Ask for a complete HGX server and check whether the memory capacity fits your model and batch size.
- Memory
- 80 GB
- Format
- SXM
- ·Existing CUDA workloads
- ·Training and inference that fit within 80 GB per GPU
H200 gives a memory-constrained CUDA workload more room before changing platforms.
H200 SXM has 141 GB of HBM3e memory and 4.8 TB/s of peak memory bandwidth per GPU. Compare the actual OEM server, power configuration, network, and support terms in the quote.
- Memory
- 141 GB
- Bandwidth
- 4.8 TB/s
- ·Large-model inference
- ·CUDA workloads limited by H100 memory
B200 is a system purchase. The server build and facility fit matter as much as the GPU count.
HGX B200 uses eight SXM GPUs with 180 GB of HBM3e each. NVIDIA supports air- and liquid-cooled partner designs. Confirm the OEM server, cooling, power, interconnect, and whether the requested quantity maps to available system configurations.
- Memory
- 180 GB
- HGX system
- 8 GPUs
- ·Blackwell training and inference
- ·Deployments planned around complete 8-GPU servers
MI300X is worth testing when model memory is a constraint and the workload can run on ROCm.
MI300X provides 192 GB of HBM3 memory per GPU. Review framework and kernel support on your actual workload before committing to an AMD server.
- Memory
- 192 GB
- Software
- ROCm
- ·Memory-heavy inference
- ·Teams prepared to validate an AMD software path
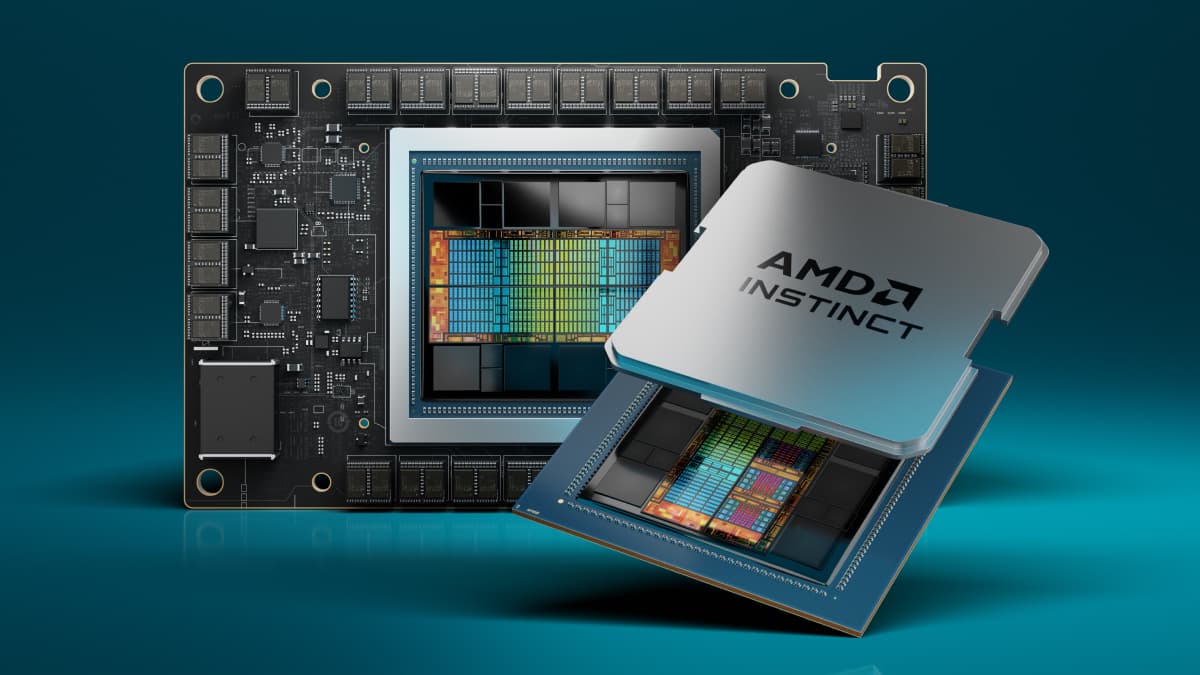
The extra HBM is useful only if the server and cooling plan fit the deployment.
MI355X provides 288 GB of HBM3e and up to 8 TB/s peak memory bandwidth per GPU. AMD specifies direct liquid cooling for this 1,400 W accelerator. Validate the exact OEM platform and facility requirements.
- Memory
- 288 GB
- Cooling
- Direct liquid
- ·Very large models on ROCm
- ·Facilities designed for liquid-cooled systems
GPU and quantity
Model, GPU count, and whether a complete server or rack is needed.
Workload
Training or inference, model size, framework, and any CUDA or ROCm requirement.
Facility
Destination, available power, rack space, and air or liquid cooling.
Timing
Target delivery date and whether an alternate configuration is acceptable.
Commercial terms
Written configuration, current price, delivery estimate, warranty, and support.
For an HGX B200 request, tell us whether the GPU count is exact or can be adjusted to complete 8-GPU systems. We can then ask suppliers about feasible server counts and configurations.
Specifications
Memory, bandwidth, format, and cooling details above come from manufacturer documentation. Check the final OEM bill of materials before ordering.
09 / 09
Send us the build you have in mind.
A rough spec is enough to start. We will work through the configuration, then confirm current pricing, delivery, and warranty terms in writing.
Request a quote