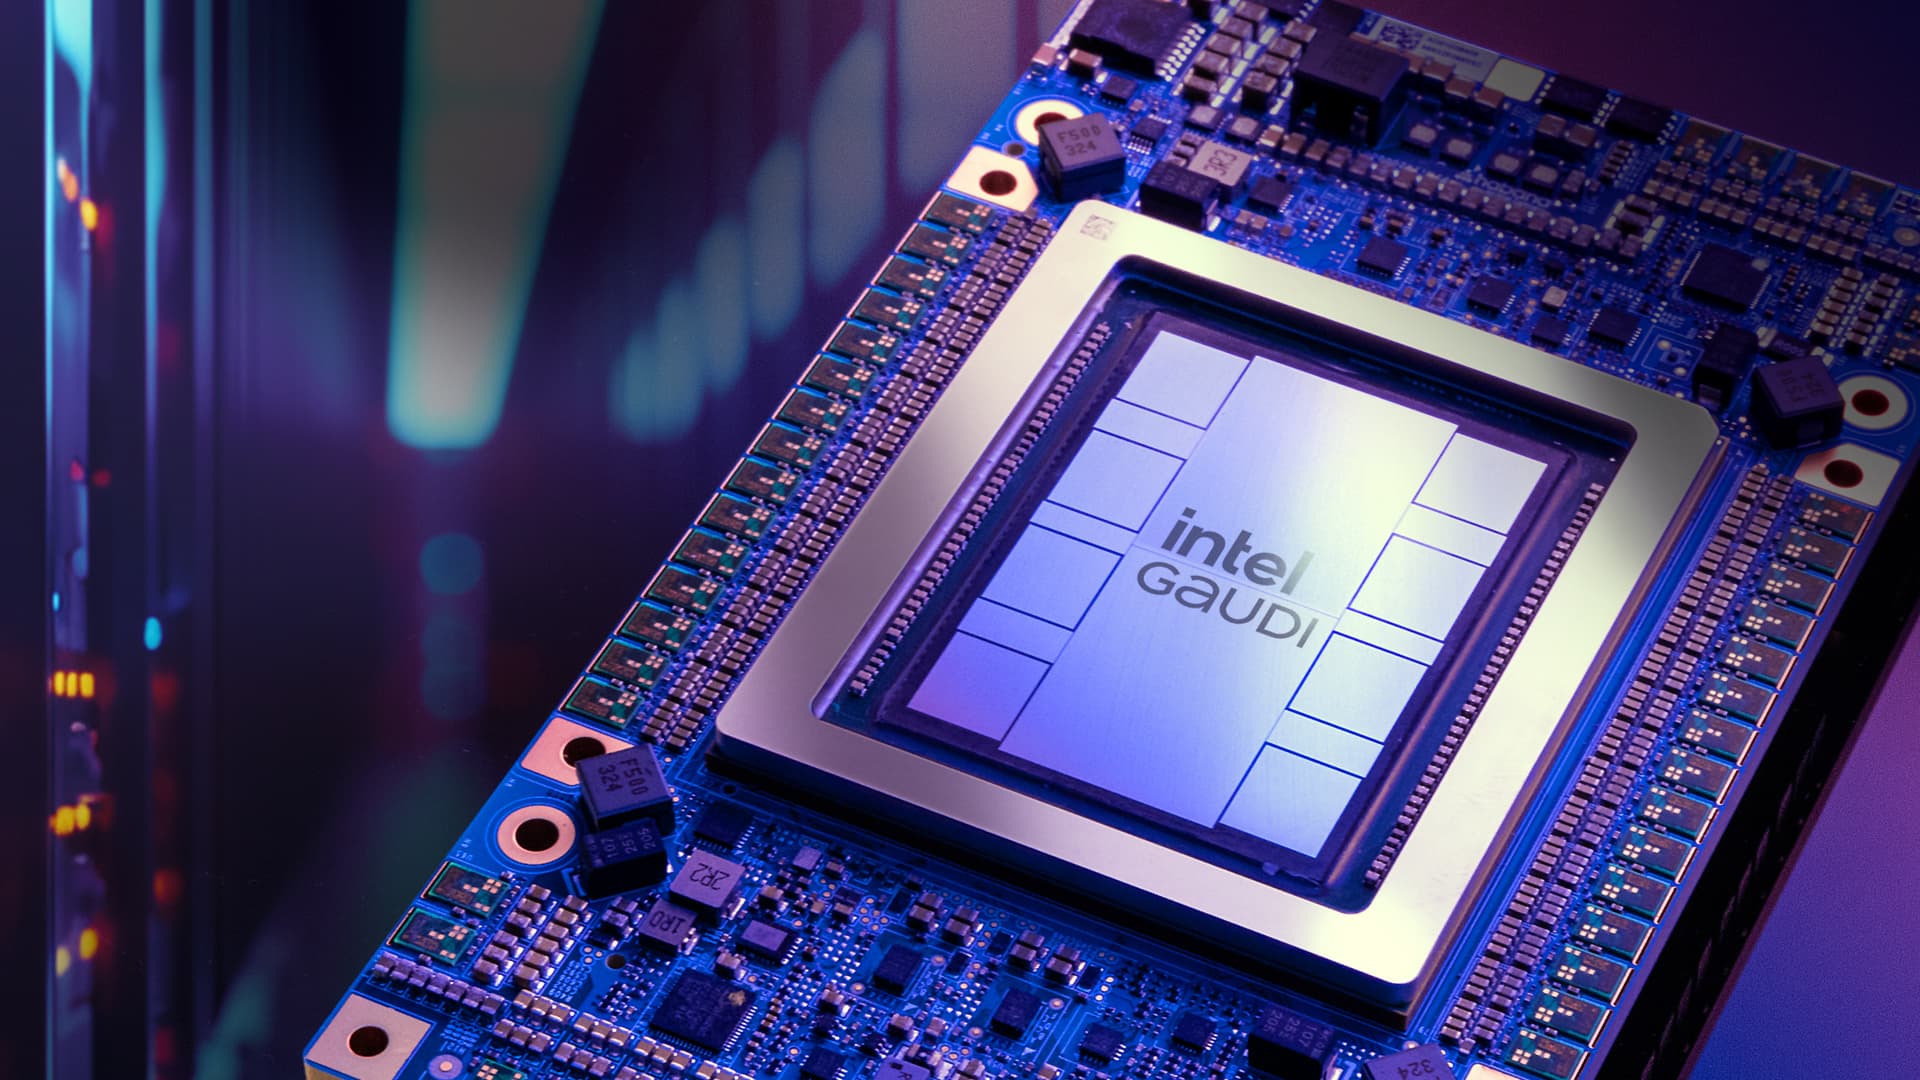
Intel Gaudi 3 AI Accelerator
Intel's third-gen AI accelerator optimized for LLM training and inference. Cost-effective alternative with Ethernet-based scaling. Contact us for evaluation units and pricing.
Price Available Upon Request
We confirm the configuration, price, delivery estimate, and warranty terms before you order.
What it's for
Intel Gaudi 3 AI Accelerator is built for training and inference of large language models and generative AI. Built on TSMC's 5nm process, Gaudi 3 combines 64 tensor processor cores, 8 matrix multiplication engines, and 128GB HBM2e at 3.7TB/s. Its real differentiator: it scales on standard 200GbE Ethernet instead of proprietary interconnects, which changes the networking bill of materials. Contact us for evaluation units and a TCO comparison.
Key Features
- ✓64 tensor processor cores (TPCs) with 8 matrix multiplication engines (MMEs)
- ✓128GB HBM2e memory with 3.7TB/s bandwidth
- ✓1.8 petaFLOPS FP8 and BF16 compute performance
- ✓Integrated 24x 200 GbE networking for scale-out
- ✓96MB on-die SRAM cache for low-latency operations
- ✓14 integrated media engines (H.265, H.264, JPEG, VP9)
- ✓TSMC 5nm process node technology
- ✓Available in PCIe (600W) and OAM (900W) form factors
Use Cases
- →Large language model training (LLaMA, GPT-style models)
- →Generative AI inference at scale
- →Computer vision and video processing
- →Recommendation systems and embeddings
- →Multi-modal AI workloads
- →Cost-optimized AI infrastructure deployment
Technical Specifications
| Architecture | Gaudi 3 (TSMC 5nm) |
| GPU Memory | 128 GB HBM2e |
| Memory Bandwidth | 3.7 TB/s |
| Tensor Processor Cores | 64 TPCs |
| Matrix Multiply Engines | 8 MMEs |
| FP8 Performance | 1.8 petaFLOPS |
| BF16 Performance | 1.8 petaFLOPS |
| On-die SRAM | 96 MB |
| Network Interfaces | 24x 200 GbE |
| Media Engines | 14 (H.265/H.264/JPEG/VP9) |
| Max TDP (PCIe) | 600W |
| Max TDP (OAM) | 900W |
| Thermal Solution | Air cooling (PCIe) / Liquid (OAM) |
| Form Factor | PCIe Gen5 AIC |
| PCIe Interface | PCIe Gen5 x16 |
Manufacturer references
Related Products
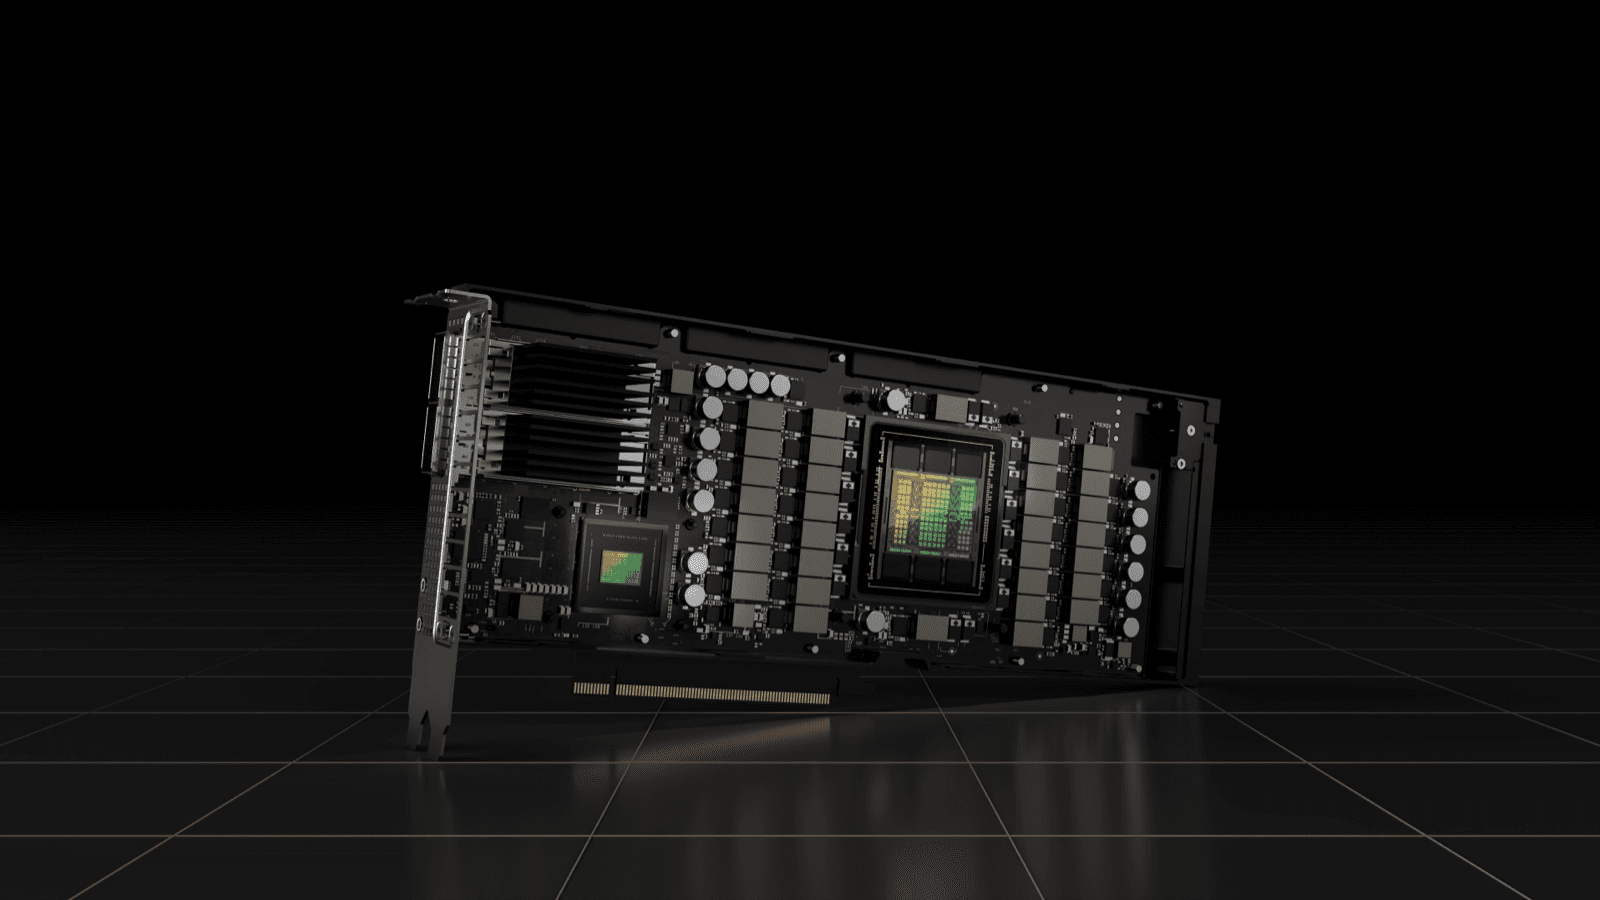
NVIDIA H100 80GB PCIe Gen5
NVIDIA H100 PCIe accelerator with 80GB of HBM2e. Fits supported PCIe server platforms for training and inference. Request a current configuration and quote.
Current quote on request

NVIDIA H100 80GB SXM5
NVIDIA H100 SXM GPU with 80GB HBM3, used in HGX server platforms. Request a complete OEM system quote with current delivery terms.
Current quote on request

NVIDIA H200 141GB HBM3e SXM5
Hopper GPU with 141GB HBM3e and 4.8TB/s bandwidth. A useful option for memory-heavy inference. Contact us for current availability and lead time.
Current quote on request

NVIDIA B200 180GB SXM
Blackwell GPU with 180GB HBM3e per GPU in 8-GPU HGX systems. Ask us for a complete OEM server quote with current availability and lead time.
Current quote on request
Recommended Reading
Related buying guides
Background on memory, power, cooling, and deployment planning.
GPU Memory Requirements for LLM Inference: How Much VRAM Do You Need?
A practical VRAM sizing guide for LLM inference: 7B, 13B, 70B, and 405B model classes, how quantization changes memory needs, and when to choose RTX 4090, L40S, H100, or H200.
AI Cluster Networking Guide: InfiniBand vs Ethernet for GPU Training
Network design is often the bottleneck in distributed training. Learn when InfiniBand is worth it, when Ethernet is enough, and how to think about oversubscription, storage traffic, and scale-out planning.
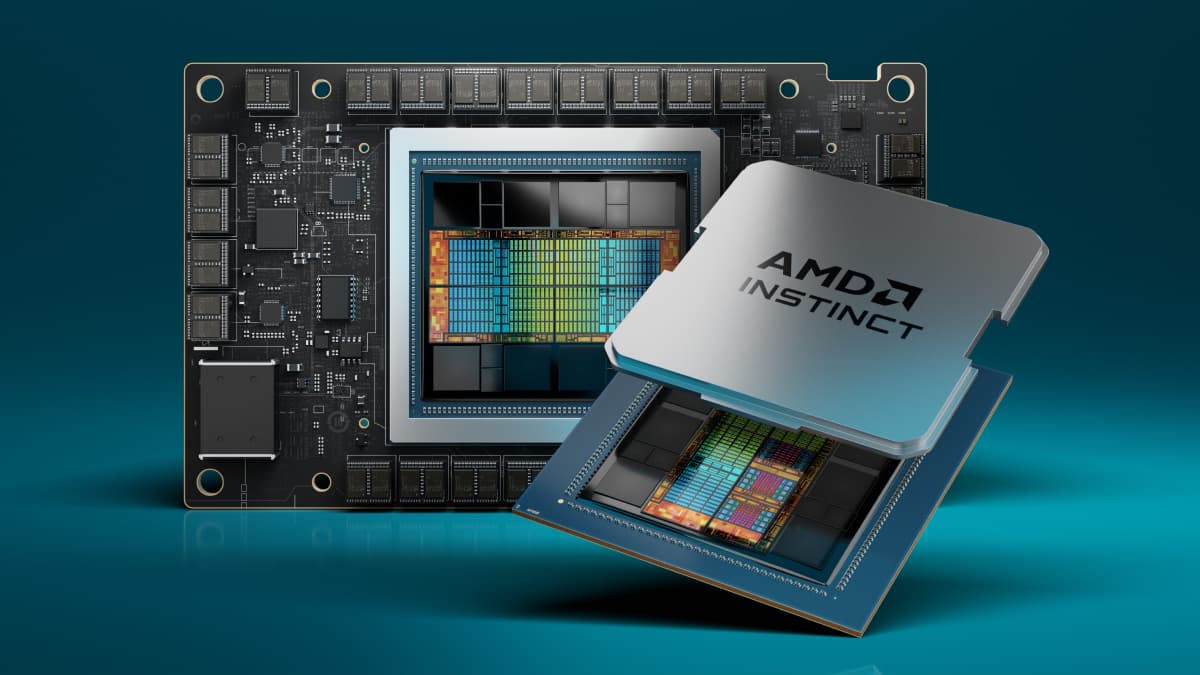
AMD MI300X for Generative AI: Where It Fits
MI300X memory, ROCm software fit, OEM server requirements, and how to compare current quotes.