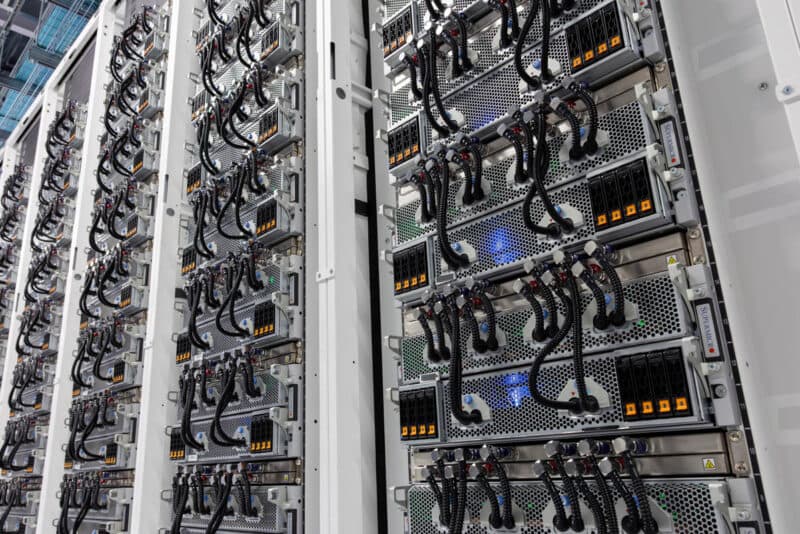
If your AI infrastructure content still sounds like "H100 vs A100" and treats 70B as the upper edge of practical deployment, it is already behind the market. Over the last twelve months, the center of gravity moved in three important ways:
- Blackwell moved from roadmap to real cloud deployment.
- AMD launched the MI350 family and made 288GB a real procurement option.
- Benchmarks and open-weight models changed what counts as a serious inference box.
This update focuses on durable signals buyers can actually plan around, not rumor-cycle noise.
TL;DR
- NVIDIA said on April 15, 2025 that Grace Blackwell systems were in full production at cloud providers like CoreWeave.
- Google Cloud made A4X generally available on May 29, 2025, giving buyers a public GB200 NVL72 option alongside A4 B200 instances.
- AMD launched the MI350 Series on June 12, 2025, and the MI350X product page confirms 288GB HBM3e, 8TB/s bandwidth, and a June 12, 2025 launch date.
- AWS put P6e-GB200 UltraServers into general availability on July 9, 2025 and made G7e generally available on January 20, 2026, which matters because Blackwell is now showing up in both rack-scale and mainstream server form factors.
- MLPerf Inference v5.0 on April 2, 2025 and MLPerf Training v5.0 on June 4, 2025 both shifted to Llama 3.1 405B-scale testing. That is a stronger market signal than vendor slides.
- OpenAI's gpt-oss launch on August 5, 2025 matters for infrastructure planning because the 120B model is designed to run efficiently on a single 80GB GPU.
The practical implication is simple: the market is splitting into three lanes rather than converging on one winner.
| Lane | Typical hardware | Best fit |
|---|---|---|
| Mainstream inference | RTX PRO 6000 Blackwell Server Edition, H100 PCIe, H200 | Production serving, enterprise RAG, multimodal apps, smaller fine-tunes |
| High-memory inference / mid-scale training | H200, MI300X, MI350X, B200 | 70B to 405B serving, larger context windows, denser batch throughput |
| Frontier rack-scale | GB200 NVL72, B200 clusters, future MI355X/Helios deployments | Trillion-parameter training, very large reasoning workloads, hyperscale clusters |
1. Blackwell Is Real Now, but It Is Not One Product
The first useful correction for buyers is to stop talking about "Blackwell" as if it were a single deployable thing.
There are now distinct Blackwell buying motions:
- Rack-scale Grace Blackwell for the largest training and reasoning systems
- B200 HGX-class systems for dense datacenter deployments
- RTX PRO 6000 Blackwell Server Edition for more conventional enterprise servers
That matters because these products land in different budgets, different facilities, and different software conversations.
Google Cloud's A4X announcement explicitly positions GB200 NVL72 for "reasoning models" and large-scale training or serving, while A4 B200 is framed as the more portable option for fine-tuning and serving. AWS made the same split in July 2025: P6e-GB200 UltraServers are for frontier-scale workloads, not general enterprise inference.
Then AWS G7e reached general availability on January 20, 2026, bringing up to 8 RTX PRO 6000 Blackwell Server Edition GPUs with 96GB each into a much more standard cloud shape. That is a commercially important development because it widens the Blackwell conversation beyond hyperscalers and model labs.
Buyer takeaway: "Blackwell availability" is no longer the question. The real question is which Blackwell tier maps to your workload and facility constraints.
2. AMD's MI350 Launch Turned Memory Back Into a Procurement Weapon
AMD launched the MI350 Series on June 12, 2025, and the MI350X product page puts the headline specs in writing:
- 288GB HBM3e
- 8TB/s memory bandwidth
- MXFP4 and MXFP6 support
- launch date of June 12, 2025
That changes planning conversations even for teams that still prefer NVIDIA, because it raises the standard for what buyers will expect in the high-memory tier.
AMD also said the rack-scale stack was already rolling into hyperscaler deployments such as OCI and would see broader availability in the second half of 2025. That is materially different from "roadmap silicon." It means MI350 is now a real alternative category for:
- long-context inference
- very large open-weight serving
- buyers who need fewer GPUs per deployment
- teams actively trying to diversify away from a single vendor
This does not erase CUDA's advantage. It does force every buyer to take the AMD memory argument seriously.
Buyer takeaway: if your workload is memory-bound before it is compute-bound, MI350-class hardware is no longer a hypothetical comparison point. It belongs in the short list.
3. MLPerf Quietly Reset the Definition of "Large Model Infrastructure"
The benchmark suite shifted with the market.
MLPerf Inference v5.0 introduced a new Llama 3.1 405B benchmark with support for 128,000-token input and output lengths. MLPerf Training v5.0 also moved to a Llama 3.1 405B pretraining benchmark, replacing the older GPT-3-based benchmark.
That matters because benchmark suites lag vendor marketing but usually track what sophisticated buyers are already trying to deploy. When MLPerf moves to 405B-scale testing, the market message is straightforward:
- 70B is no longer the outer edge of "serious"
- memory footprint and interconnect matter more than they did one year ago
- facilities planning is inseparable from model planning
If your editorial content still assumes 7B, 13B, and 70B are the main sizing tiers, it will age badly.
Buyer takeaway: the modern sizing conversation needs at least three checkpoints:
- Can the model fit?
- Can it fit with the context window, KV cache, and batch target you actually need?
- Can the network and rack design keep up once the model stops being a single-box problem?
4. Open-Weight Reasoning Models Lowered the Minimum Useful Inference Box
The other structural shift is not at the top end. It is at the low end.
OpenAI's gpt-oss release on August 5, 2025 made a new point explicit: the gpt-oss-120b model was designed to run efficiently on a single 80GB GPU, while gpt-oss-20b can run in 16GB.
That does two things to the hardware market:
- it increases the usefulness of existing 80GB-class infrastructure
- it creates a bigger practical market for 48GB to 96GB inference systems
Not every buyer needs GB200 or an 8-GPU HGX box to ship useful reasoning features anymore. A lot of teams can now choose between:
- a single 80GB inference node
- a 2x H100 or H200 serving box
- a 96GB-per-GPU Blackwell server edition deployment
This is why the middle of the market is getting more interesting, not less.
Buyer takeaway: the floor for meaningful local or private inference dropped, but the ceiling for frontier training moved up at the same time. That is why the market feels more fragmented right now.
5. Public Cloud Pricing Signals a Segmented Market, Not a Settled One
Public pricing pages are imperfect, but they still reveal where providers think demand is strongest.
On the public pages reviewed in April 2026:
- CoreWeave's pricing page listed 8x H100 at $49.24/hour, 8x H200 at $50.44/hour, and 8x RTX PRO 6000 Blackwell Server Edition at $20.00/hour
- Lambda's pricing page listed H100 SXM instances at $3.99 per GPU/hour and B200 SXM6 at $6.69 per GPU/hour, while its 1-Click clusters showed H100 at $6.16 per GPU/hour and B200 at $9.86 per GPU/hour
This is not an apples-to-apples benchmark comparison, but it is still useful.
What these public prices suggest
| Signal | Why it matters |
|---|---|
| H100 and H200 are still priced very closely on some clouds | Hopper has not been economically displaced across the board |
| B200 still commands a meaningful premium | Blackwell value is real, but buyers are still paying for it |
| 96GB Blackwell server editions are becoming the practical middle tier | Enterprise inference has a new lane between workstation-class gear and HGX racks |
| Providers still publish multiple generations side by side | The market is not standardizing on one GPU family yet |
Buyer takeaway: if your workload does not truly need B200 or GB200, there is still room to make a rational H100, H200, or 96GB-class Blackwell decision instead of chasing the newest platform by default.
6. What Buyers Should Do Right Now
If you are buying for inference
- Treat 80GB to 96GB as the first serious decision tier, not the entry-level afterthought
- Size for context window and concurrency, not just model parameter count
- Compare cost per useful deployment, not just cost per GPU
If you are buying for training
- Separate single-node training from multi-node cluster planning
- Budget for power, cooling, and network as first-order design inputs
- Do not evaluate B200, GB200, or MI350-class systems without a facilities conversation
If you are refreshing the site content
- Publish more content around 405B-class planning, 96GB inference servers, Blackwell cloud availability, and rack-level design
- Keep older H100 material, but stop writing as if it is the only serious buyer decision
The Current Shape of the Market
The cleanest way to describe the market in April 2026 is this:
- Blackwell is here
- Hopper is still commercially relevant
- AMD is stronger where memory is the constraint
- Open-weight reasoning models widened the useful mid-market
- 405B-scale planning is now mainstream enough to show up in benchmark suites
That is not a stale market. It is an actively re-tiering one.
If you need help translating that into an actual hardware plan, start with our GPU memory sizing guide, buy-vs-rent analysis, or contact us for a workload-specific recommendation.
Frequently Asked Questions
Is H100 still a valid purchase in 2026?
Yes. Public cloud pricing still shows H100 sitting very close to H200 in some environments, and newer open-weight reasoning models make 80GB-class hardware more useful than it looked a year ago.
When do I actually need Blackwell?
When your workload is constrained by throughput, memory domain size, or cluster-scale efficiency enough to justify the premium. If you are serving moderate open models or building a first private inference tier, you may not need it yet.
Why does MI350 matter if my team prefers CUDA?
Because it changes the competitive baseline for memory-rich accelerators. Even NVIDIA-first buyers now need to explain why they are paying more for less memory per GPU.
What is the single biggest reason blog content in this category goes stale?
It describes product families but ignores market structure. The content that ages best explains what changed in availability, pricing, benchmark scale, and deployment patterns.

